How to Evaluate AI System Performance Before Going Live
Why Pre-Deployment Testing Matters for Enterprise AI Solutions
Rolling out an AI system into production without a thorough performance check is a gamble that few organizations can afford. A model that works well in a lab may behave unpredictably under real-world data loads, latency constraints, or hardware limits. For enterprise AI solutions, the gap between a proof-of-concept and a reliable service often comes down to how systematically the team tests performance before deployment. This article walks through the practical steps for assessing AI system performance, with attention to the hardware and infrastructure that support it.
Step 1: Define Performance Metrics That Match Your Business Goals
Before running any tests, you need to know what "good" looks like for your use case. Different AI tasks care about different measures. A real-time recommendation engine might prioritize low latency, while a batch-processing image classifier could focus on throughput. Start by listing the key performance indicators that matter for your application:
- Throughput: how many inferences or transactions the system can handle per unit of time.
- Latency: the time it takes from receiving a request to returning a response, often measured at percentiles (p50, p95, p99).
- Memory capacity: how much data the model and its supporting structures can hold in RAM or VRAM without swapping.
- Power consumption: important for data center costs and thermal management, especially when scaling up.
- Scalability: how performance changes as you add more hardware or users.
Once you have the metrics, set acceptable thresholds. For example, "p99 latency must stay under 200 milliseconds under 1000 concurrent requests." These numbers become the pass-fail criteria for your deployment decision.
Step 2: Benchmark Against Representative Workloads
A generic benchmark like a standard image classification dataset tells you little about how your system will behave on your actual data. Instead, build a test set that mirrors the production distribution: same data types, same size ranges, same request patterns. If your AI system processes text from customer support tickets, use a sample of those tickets, not a curated academic corpus.

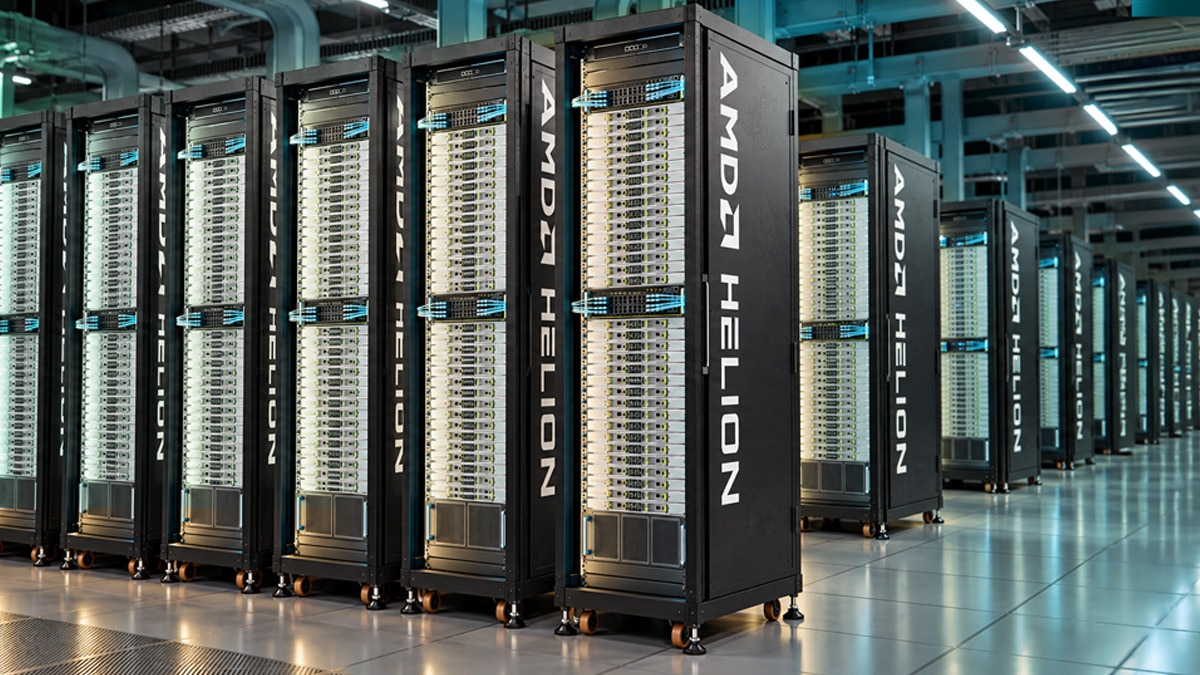
Run the benchmarks on the hardware you intend to use in production. If you are evaluating different hardware options, test each one with the same workload and measure the same metrics. Pay attention to how the hardware handles parallel processing and memory bandwidth. For instance, efficient hardware for AI workloads often comes down to the balance between compute units (GPUs or NPUs) and memory bandwidth. A mismatch can cause the compute units to stall while waiting for data, hurting throughput and latency.
Step 3: Test for Reliability Under Stress
AI systems in production rarely face a steady, gentle load. They get spikes during business hours, flash sales, or viral moments. Stress testing means pushing the system beyond its expected peak load to find where it breaks or degrades. Gradually increase the request rate while monitoring latency, error rates, and memory usage. Watch for signs of thrashing, where the system spends more time swapping data than processing it.
A useful technique is the "soak test": run the system at a moderate load for several hours or days. Some performance issues only appear after the hardware warms up, caches fill, or memory fragments. If your system uses GPUs, monitor their temperature and clock speeds under sustained load. Thermal throttling can quietly reduce throughput over time.
Step 4: Evaluate Scalability Across Nodes
For enterprise AI solutions that need to serve many users or process large datasets, scalability is critical. Test how well the system performs when you add more compute nodes or upgrade components like CPUs, GPUs, or memory. Measure both strong scaling (fixed problem size, more nodes) and weak scaling (problem size grows with nodes). Look for bottlenecks in the network, storage, or software stack that prevent linear scaling.
Distributed AI systems introduce new failure modes: node communication overhead, synchronization delays, and load imbalance. Run your scalability tests with the same data distribution and model parallelism you plan for production. The goal is to understand the cost per additional unit of performance and to confirm that the system can handle future growth.
Step 5: Profile Hardware Utilization and Power Efficiency
Modern AI hardware is powerful but can be expensive to run. Profiling helps you see whether your system is using the hardware effectively. Check GPU utilization, memory bandwidth usage, and CPU overhead. Low utilization might mean the model is not well optimized for the hardware, or that the software stack has a bottleneck. Conversely, high utilization with high latency suggests the hardware is saturated and you need more capacity or a different architecture.
Power consumption is a growing concern in data centers. Measure watts per inference or watts per transaction. Efficient hardware for AI workloads can reduce both operational costs and cooling requirements. If your tests show that a different hardware configuration delivers the same throughput with significantly less power, that is a strong factor in the deployment decision.
Step 6: Validate Model Accuracy and Drift Resistance
Performance metrics like latency and throughput are meaningless if the model's predictions are wrong. Before deployment, run a comprehensive accuracy evaluation using the test set. But also test with data that is slightly different from the training set, to see how the model handles distribution shift. This is especially important for AI systems that will process user-generated content, which changes over time.
Monitor the model's confidence scores and error rates under different conditions. If accuracy drops when latency is high, the system may be making trade-offs that hurt the user experience. Some systems degrade gracefully by returning a fallback response or a cached result; test that path to ensure it works reliably.
Step 7: Run a Controlled Canary Deployment
Once your lab tests pass, the final step before full rollout is a canary deployment: route a small percentage of live traffic to the new system while monitoring all metrics in real time. This catches issues that only appear with real user behavior, such as unexpected input formats, network variability, or hardware quirks. Keep the canary running long enough to cover typical usage cycles, including peak periods.
Have a rollback plan ready. If any metric crosses the warning threshold, redirect traffic back to the previous system and investigate. Document the findings and adjust your benchmarks or hardware configuration accordingly.
What to Watch Out For at Each Step
Throughout this process, be aware of common pitfalls. One is benchmarking on hardware that is not representative of the production environment. Another is focusing on a single metric, such as peak throughput, while ignoring tail latency or memory leaks. Also, avoid testing only with ideal data: real-world inputs have noise, missing values, and outliers that can trip up a model or cause hardware to work harder than expected.
Finally, remember that performance assessment is not a one-time event. As you update models, add features, or change hardware, repeat these steps. A system that passed all tests six months ago may behave differently with a new model version or a different data distribution. Regular evaluation keeps your enterprise AI solutions reliable and cost-effective over the long term.